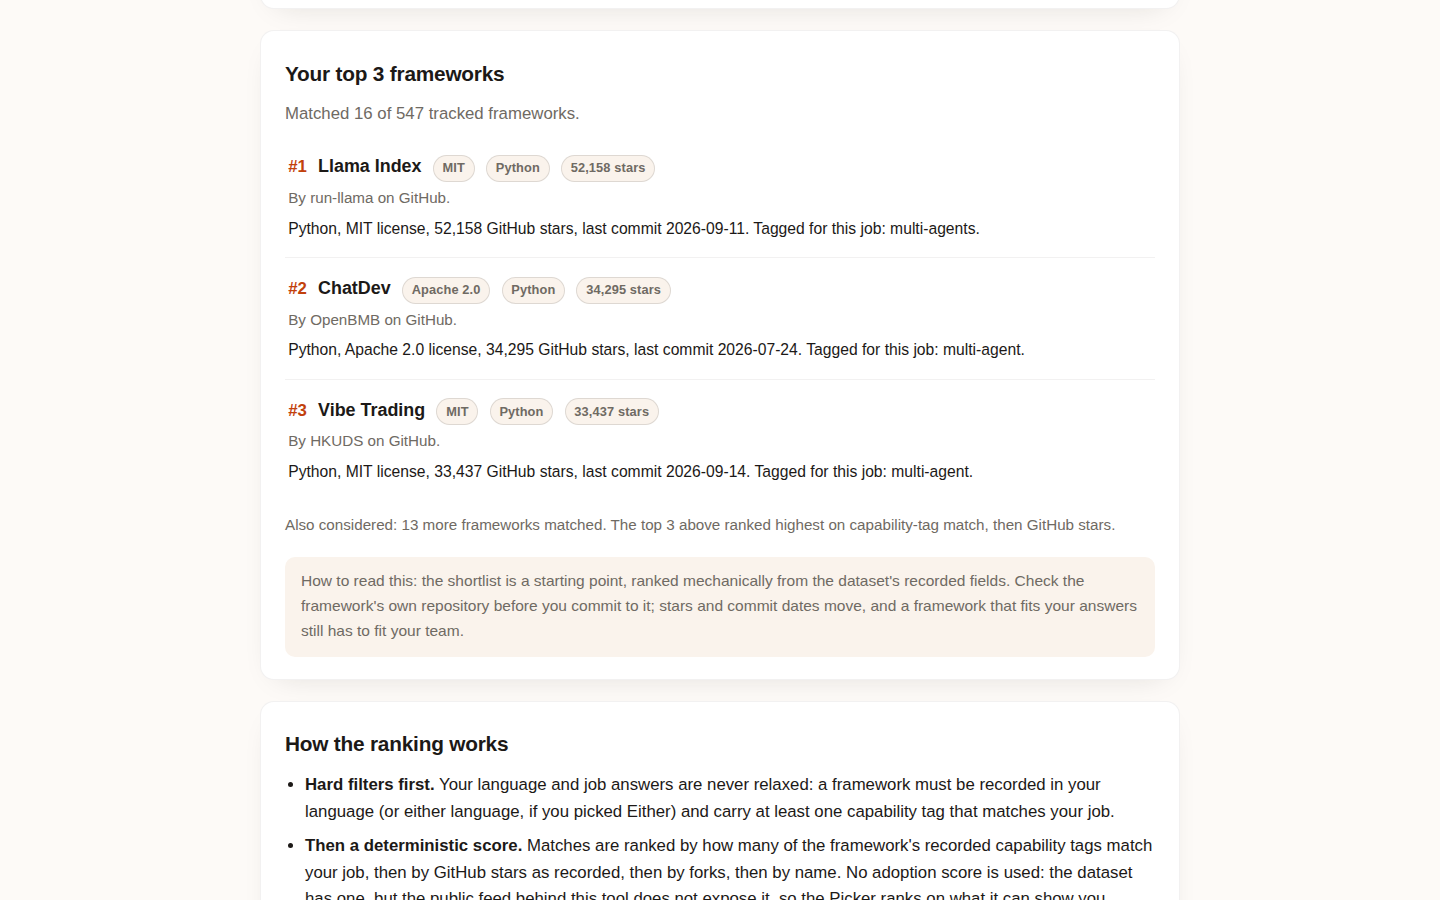
A picker is only as good as the questions you bring to it. FrameworkPicker takes 4 answers and ranks 547 frameworks down to a top 3. Here are six runs worth doing, starting with a real one: Python, multi-agent team, must be permissive, actively maintained only. Sixteen frameworks matched. The top 3 were Llama Index (MIT, 52,158 stars, last commit September 2026), ChatDev (Apache 2.0, 34,295 stars), and Vibe Trading (MIT, 33,437 stars). Now yours.
1. The permissive Python multi-agent team (the run above)
This is the startup-safe default: a license your lawyers will wave through, the biggest ecosystem, and code that moved this quarter. Note what the filter did: 547 frameworks became 16 candidates before ranking even started. If your shortlist still feels long, that is the ranking doing its job; read the cards top down. The written counterpart is our multi-agent orchestration comparison.
2. Fresh code only, any ecosystem
Set momentum to actively maintained and everything else loose. Agent frameworks die quietly; a repo with no commit in a year is a dependency you will maintain yourself. This run doubles as a health scan of the field, and it pairs well with our adoption trends analysis of the same dataset.
3. The "can we ship this at work" screen
License set to must be permissive, job set to your real use case. Copyleft surprises surface here, before legal finds them in a review. Once a winner emerges, the next step is not code, it is the AI agent security audit, the most searched guide on this site, because a permissive license says nothing about safe defaults.
4. The visual builder detour
Language on Any, job on workflow automation, and the shortlist tilts toward the visual end of the dataset. Then read the head-to-head before you commit: Flowise vs Langflow vs n8n is our closest-ranking comparison (the langflow vs n8n call is one of the closest in the dataset), backed by the no-code agent builder top 10.
5. The local LLM build
Running models on your own hardware narrows the field brutally: you need a framework that treats local inference as a first-class citizen, not a plugin. Run job on general purpose with momentum strict, then cross-check against our guide to the best framework for local LLMs, where the pluggable ones win for exactly this reason.
6. Change one answer at a time
The picker is a diagnostic tool if you drive it that way. Re-running the same answers is free, so vary a single dial: drop the license rule and watch what enters; loosen momentum and count the ghosts. Each delta teaches you what your constraints cost. And keep the stars in perspective: our most starred repos post is blunt about what a star count cannot tell you. The raw material behind all of it lives on GitHub's AI agents topic.
Two picks a day are free, changed answers count as a new pick, and the tool never relaxes your language or job filters without telling you on the card. When the shortlist is set and the agent is built, ShipSafe at AIForWork audits the workflow before it ships. Start with the run that matches your project: FrameworkPicker.